国庆节10月1日
--

用 requests 库发送 HTTP 请求:TIOBE 编程语言排行榜入门程序,请求、解析、遍历数据的完整流程
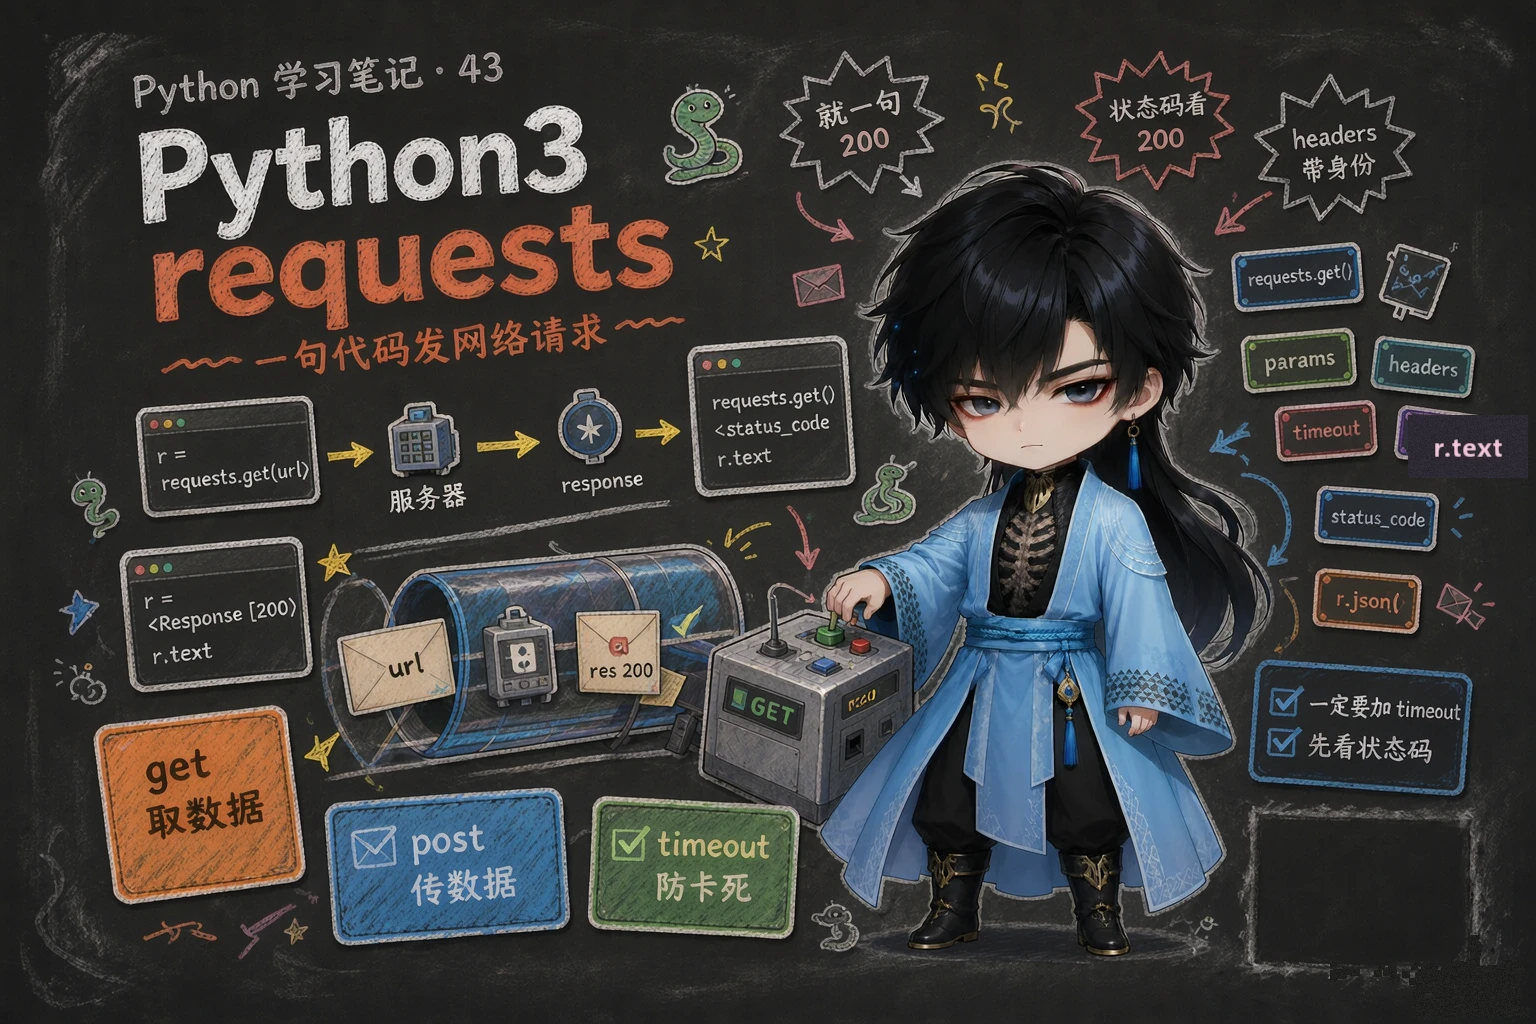
Requests 库是 Python 中最流行、最优雅的 HTTP 客户端库,让 Python 代码发送 HTTP 请求变得极其简单。
在爬虫五步流程里,它负责第一步”发送 HTTP 请求”。
安装:
pip install requests目标:抓取 https://www.tiobe.com/tiobe-index/ 的编程语言排行榜。
动手前先做三件事:
robots.txt(https://www.tiobe.com/robots.txt),明确哪些资源允许抓取import requestsfrom lxml import html
# 定义 urltarget_url = "https://www.tiobe.com/tiobe-index/"
# 发送请求, 获取数据response = requests.get(target_url)
# response.text 就是服务器返回的 HTML 源码(字符串)document = html.fromstring(response.text)
# 解析表头(Xpath 语法,下一节细讲)th_list = document.xpath("//*[@id='top20']/thead/tr/th/text()")print(th_list)
# 解析表格中的数据(遍历每一行)tr_list = document.xpath("//table[@id='top20']/tbody/tr")for tr in tr_list: td_list = tr.xpath("./td/text()") print(td_list)| 代码 | 说明 |
|---|---|
requests.get(target_url) | 向目标网址发 GET 请求,返回一个 Response 对象 |
response.text | 服务器返回的 HTML 源码(字符串) |
html.fromstring(response.text) | 把 HTML 字符串解析成”文档对象”,之后才能用 Xpath 查询(来自 lxml 库) |
document.xpath("...") | 用 Xpath 表达式在文档里定位元素、取文本 |
//table[@id='top20'] | 任意位置找 id 为 top20 的 table([@属性='值'] 是 Xpath 的属性过滤) |
tr.xpath("./td/text()") | 在当前 tr 节点下找直接子元素 td 并取文本(./ 表示当前节点) |
正式项目里给请求加超时:requests.get(url, timeout=60)。不加的话,对方服务器没响应时你的程序会一直卡着。
pip install requestsresponse = requests.get(url)response.texthtml.fromstring(response.text)(来自 lxml 库)//*[@id='top20'] 的意思是:从任意位置找 id 为 top20 的任意元素tr.xpath("./td/text()") 里的 ./ 表示从当前节点下查找 2-1 抓一个网页看看源码
用 requests 请求 https://www.itcast.cn,把返回的 HTML 源码前 200 个字符打印出来。
一级 · 思路:发请求 → 拿到响应 → 字符串切片
二级 · 方法:requests.get(url) / response.text
三级 · 骨架:print(response.text[:____])
# 2-1import requests
response = requests.get("https://www.itcast.cn", timeout=60)print(response.text[:200]) 2-2 抓 TIOBE 榜单的表头
请求 TIOBE 排行榜页面,解析出榜单表格的表头(一行列表),加上 timeout=60。
一级 · 思路:请求 → 解析成文档对象 → Xpath 取表头
二级 · 方法:html.fromstring / document.xpath("//*[@id='top20']/thead/tr/th/text()")
三级 · 骨架:response = requests.get(url, timeout=____)
# 2-2import requestsfrom lxml import html
response = requests.get("https://www.tiobe.com/tiobe-index/", timeout=60)document = html.fromstring(response.text)th_list = document.xpath("//*[@id='top20']/thead/tr/th/text()")print(th_list)2-3 请求失败也要优雅 把 2-2 的请求用 try/except 包住:网络出问题时打印”请求失败:原因”,程序不崩溃。可以用一个不存在的域名(如 https://www.this-domain-not-exist-12345.com)来测试。
一级 · 思路:网络请求随时可能失败(超时、连不上、域名不存在),失败时要有兜底
二级 · 方法:try ... except Exception as e(第 25 篇异常处理)
三级 · 骨架:except Exception as e:\n print(f"请求失败: {e}")
# 2-3import requestsfrom lxml import html
try: response = requests.get("https://www.tiobe.com/tiobe-index/", timeout=60) document = html.fromstring(response.text) print(document.xpath("//*[@id='top20']/thead/tr/th/text()"))except Exception as e: print(f"请求失败: {e}")如果你喜欢,那么欢迎来到我的世界!
了解更多暂未播放